Integrated AI racks

Integrated AI Racks. Engineered for Your Deployment.

SIDERA designs and builds project-specific AI rack configurations combining compute, network infrastructure, storage, management and facility interfaces. Final system configurations are defined according to workload, technical qualification and component availability.

Reference configurations — final architecture defined per project

Choose a starting point. Define the final system through qualification.

We work closely with the customer to design a suitable AI rack configuration around workloads, power, cooling, networking, supplier availability, qualification and acceptance requirements.

AHigh-memory inference
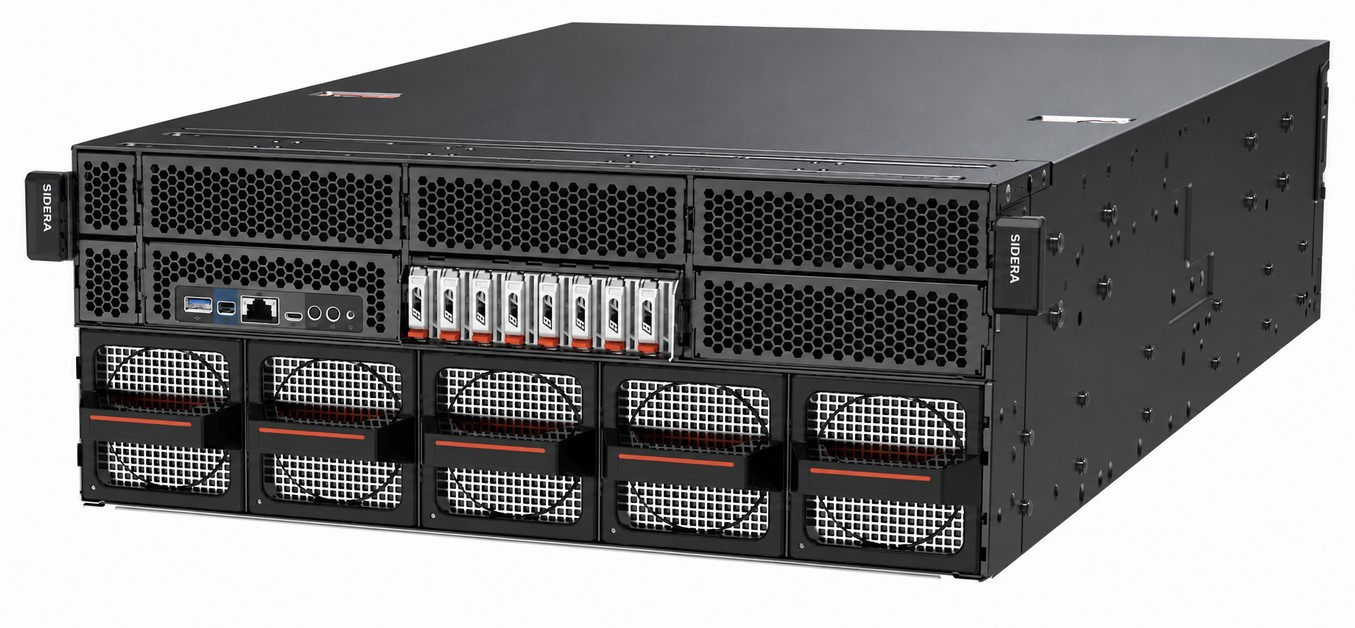
SIDERA H200 NVL compute node

AI Rack 32 H200 NVL

  • 32 × H200 NVL GPUs
  • 141 GB HBM3e per GPU
  • 4 × eight-GPU compute nodes
  • Dual 400 GbE A/B fabric rails

Long-context inference, RAG, reasoning, private model hosting and selected fine-tuning workloads.

Reference configuration · final design and availability on request

BEnterprise & visual AI
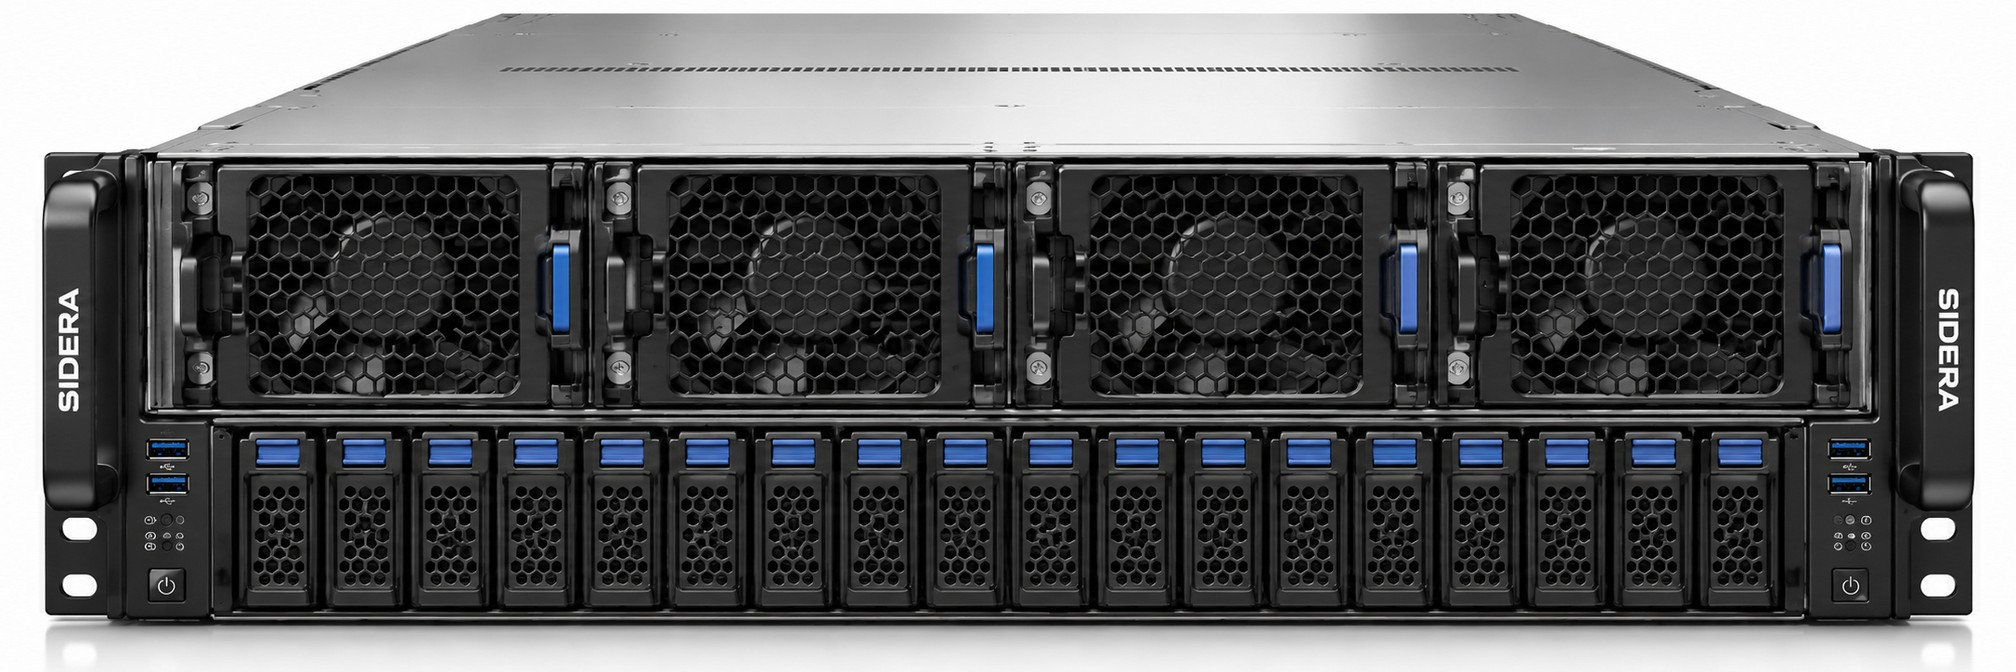
Rear view of the SIDERA RTX PRO 6000 Blackwell compute node

AI Rack 32 RTX PRO

  • 32 × RTX PRO 6000 Blackwell GPUs
  • 96 GB GDDR7 ECC per GPU
  • 4 × eight-GPU compute nodes
  • Dual 400 GbE A/B fabric rails

Enterprise inference, visual AI, digital twins, simulation and professional GPU workloads.

Reference configuration · final design and availability on request

CScale-up AI compute
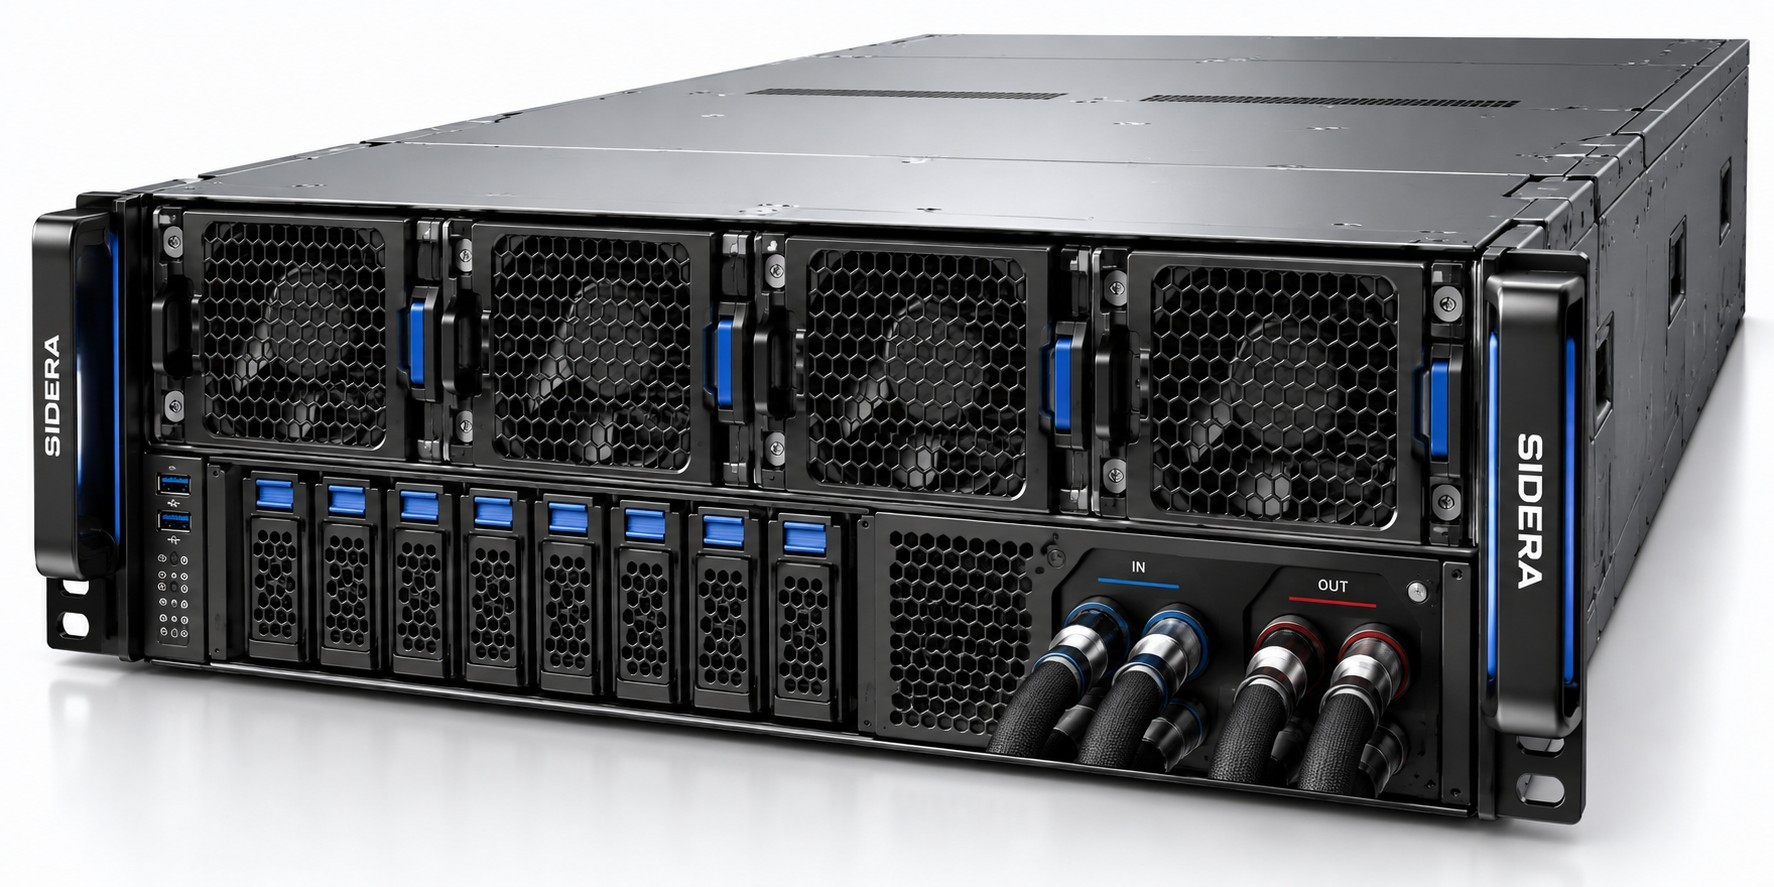
SIDERA liquid-cooled HGX B300 compute node

AI Rack 32 HGX B300

  • 32 × B300 GPUs
  • 288 GB HBM3e per GPU
  • 4 × eight-GPU HGX nodes
  • Liquid-cooled NVLink scale-up domains

Training, fine-tuning, distributed inference and compute-intensive scientific workloads.

Reference configuration · final design and availability on request

Order-defined architectureReference configurations are the starting point—not a fixed bill of materials.

Exact hardware and software releases, interconnect topology, power and cooling, qualification, acceptance testing and service scope are agreed for each project.

Explore rack integration
Pre-configured inference software

SIDERA Elastic GPUby ATOM

Scale inference capacity before adding GPUs.

SIDERA pre-configures this software layer as an option for qualified NVIDIA GPU inference environments. It dynamically allocates capacity across realtime, batch and interactive workloads so the available GPU fleet can respond to changing demand more efficiently.

Commercial advantageIncrease useful capacity, potentially defer additional GPU purchases and reduce infrastructure acquisition cost.
Evaluate it on your workload
2×requests within SLASame 2 nodes × 8 H100 GPUs
+27%more inferenceOn the same GPU fleet
21–63×faster model startAcross 9 measured configurations
Illustrative capacity equivalentPotentially up to 50% lower GPU requirement*

*Derived from ATOM’s 2× requests-within-SLA benchmark on the same 16-H100 fleet. This is not a universal cost-saving guarantee. Actual GPU requirements and economics depend on workload behavior, latency targets, topology, software compatibility and successful project qualification.

ATOM-reported benchmark results. SIDERA validates applicability on the customer’s workload before including the software and any expected capacity benefit in a final configuration.

How a SIDERA AI Rack Is Defined

The final configuration is established through a confirmed engineering and commercial process.

  1. 1

    Identify workload and AI software requirements.

  2. 2

    Select an appropriate accelerator configuration.

  3. 3

    Establish a supported network architecture.

  4. 4

    Define storage and management requirements.

  5. 5

    Confirm power and cooling compatibility.

  6. 6

    Validate supplier availability and integration scope.

  7. 7

    Agree acceptance testing and delivery conditions.

Architecture Qualification & Support

Interoperability is not the same as system certification.

Final accelerator, interconnect, software and network configurations are selected according to project requirements and applicable vendor support conditions. Product-level interoperability does not imply certification of the complete system. Qualification and support responsibilities are confirmed for each project.

GPU back-end fabric, front-end or in-band data, storage, and management networks may have different requirements. A technically interoperable switch is not presented as a substitute within an NVIDIA validated configuration unless the exact platform and configuration are documented by the applicable vendor.

AI rack architecture review

Share the workload, facility and operating requirements.

Request an architecture review

Product selection · Configuration review · Project-defined scope